How do modern organizations unseat data silos, streamline analytics, and build audit-ready data pipelines.
Organizations often struggle to turn growing volumes of data into practical insights because information is scattered across multiple systems. Effective data integration in data mining helps businesses combine data from diverse sources into a unified and reliable view. By connecting databases, cloud platforms, and applications, enterprises can improve data quality management, strengthen analytics, and achieve true operational efficiency.
The 21st century has brought the age of digital gold, where data drives innovation, globalization, and business success. However, organizations often struggle to turn growing volumes of data into practical insights because information is scattered across multiple systems.
Effective data integration in data mining helps businesses combine data from diverse sources into a unified and reliable view. By connecting databases, applications, cloud platforms, and other systems, organizations can improve data quality management, strengthen analytics, and make faster, more informed decisions.
Understanding Data Integration in Data Mining
Data integration in data mining is the process of collecting, combining, transforming, and harmonizing data from multiple heterogeneous sources to create a consistent and meaningful view. These sources may include databases, data warehouses, data cubes, flat files, cloud applications, enterprise systems, and transactional platforms.
Without integration, valuable information remains isolated in separate systems, making it difficult for analysts and decision-makers to identify patterns or relationships. A well-designed integration strategy eliminates these data silos and provides a reliable foundation for business intelligence, reporting, predictive analysis, and advanced analytics.
Key Aspects of Data Integration Several important processes contribute to successful data integration. The Global Schema, Source Schema, and Mapping Schema approach establishes relationships between different data structures and provides a standardized framework for accessing information.
During extraction and transformation, raw data is cleaned, formatted, validated, and standardized to ensure compatibility. Schema integration aligns structures from different systems, while data loading and consolidation move processed information into centralized repositories such as data warehouses.
Organizations must also address duplicate records, missing values, inconsistent formats, and conflicting information. As data volumes increase, scalability and performance optimization become equally important for maintaining efficiency with data integration.
Data Quality Management and Conflict Resolution
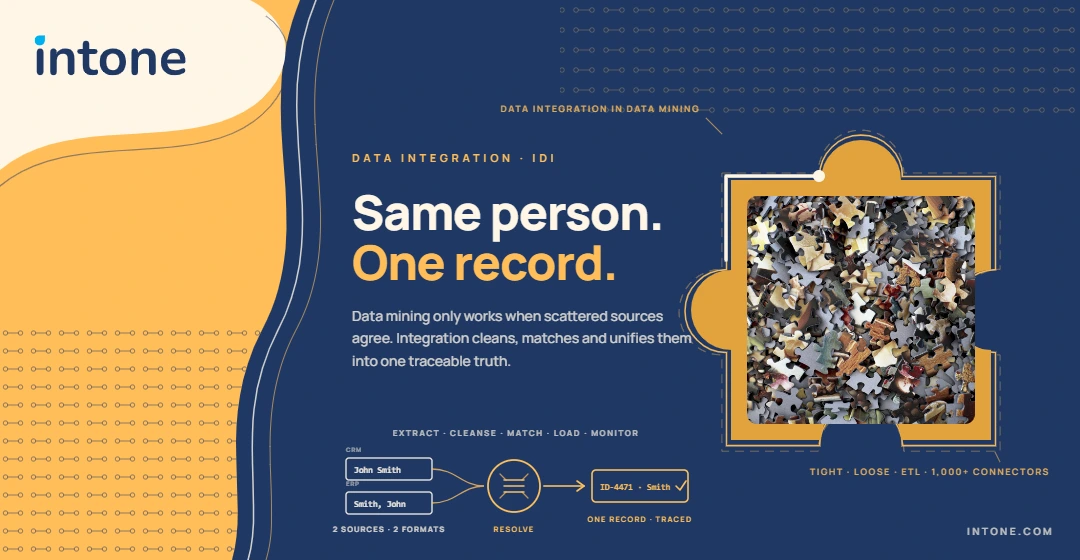
Data quality management is an essential part of the integration process because inaccurate or inconsistent information can negatively affect analytics and business decision-making. Data from different systems may use different formats, naming conventions, measurement units, or identifiers. For example, one system may record a customer as “John Smith,” while another may use “Smith, John.”
Integration processes must identify these differences and determine whether the records represent the same entity. Data cleansing, validation, deduplication, entity resolution, and record linkage can help organizations create more accurate and dependable datasets for analysis.
Data Integration Approaches There are two traditional approaches to data integration: tight coupling and loose coupling. The appropriate method depends on an organization’s data architecture, processing requirements, scalability needs, and analytical objectives. Both approaches are designed to provide access to information from multiple sources, but they differ in where data is stored and how queries are processed. Understanding these differences allows an enterprise to select an integration model that supports its operational and analytical requirements.
Tight Coupling
In tight coupling, data from different source systems is extracted, transformed, and loaded into a centralized physical location, commonly a data warehouse. ETL—Extraction, Transformation, and Loading—is used to prepare information before it is stored for reporting and analysis.
This approach provides users with a consolidated dataset and can simplify reporting, historical analysis, and business intelligence. It is particularly useful when organizations require consistent data structures and centralized governance. However, maintaining large centralized environments can require significant infrastructure, processing capacity, and ongoing data management.
Loose Coupling
Loose coupling takes a different approach by allowing users or applications to submit queries through an interface that translates those requests into a format that individual source databases can understand. Instead of physically moving all data into one repository, information generally remains in the original source of systems.
Results are retrieved when required and presented to the requesting application or user. This approach can reduce the need for large-scale data movement and may be useful when organizations need access to distributed information while preserving existing source-system architectures.
Common Issues in Data Integration Organizations can encounter several challenges when integrating data from heterogeneous sources. Entity identity is one major concern because the same real-world customer, product, employee, or transaction may be represented differently across systems. Metadata analysis, standardized identifiers, and entity resolution can help organizations correctly match records.
Structural integration is another challenge because functional dependencies and referential constraints in a source system may not align with those of the target environment. Successful integration therefore requires careful schema analysis and mapping before information is consolidated.
Redundancy, Duplication, and Correlation
Redundancy occurs when the same information is stored or represented multiple times, sometimes through attributes that can be derived from other fields. Correlation analysis can help identify relationships between attributes and determine whether certain data elements are unnecessary or duplicative.
Duplicate tuples can also appear when denormalized tables are used as sources. Record linkage, fuzzy matching, entity resolution, deduplication, and data cleansing techniques help identify and remove duplicate records. Reducing redundancy improves data reliability while also making analytical processing more efficient.
Data Conflict Detection and Resolution
Data conflicts occur when information from different sources does not match. A customer address, product description, financial value, or status may differ between systems because of inconsistent update schedules, data-entry practices, or formatting standards.
Integration processes should establish rules for detecting and resolving these conflicts. Organizations may prioritize information from a designated master system, use timestamps to identify the most recent record, or apply validation rules to determine which value should be retained. Proper conflict resolution is essential for creating trustworthy datasets and avoiding misleading analytical results.
Continuous Controls Monitoring and Data Integration Modern organizations also need to consider governance, compliance, and operational oversight when integrating data. Continuous controls monitoring can complement data integration by continuously evaluating controls and identifying potential exceptions across connected systems.
When integrated data is accurate, timely, and traceable, organizations can improve monitoring and respond to potential issues more quickly. Combining integration capabilities with continuous controls monitoring can therefore support stronger governance, improved visibility, and better risk management across an enterprise.
Enterprise Integration Tools for Modern Data Environments Modern enterprise environments often contain cloud applications, legacy databases, SaaS platforms, APIs, data warehouses, and specialized business applications. Managing connections between these systems manually can become complex and inefficient.
Modern enterprise integration tools simplify this process by providing pre-built connectors, automated workflows, transformation capabilities, monitoring, and centralized management. Analytics platforms can then consume integrated information to deliver dashboards, reports, forecasts, and other analytical outputs. Choosing scalable integration tools can help organizations reduce manual effort while supporting changing business requirements.
Why Choose Intone Data Integrator (IDI)?
The data integration market continues to grow as organizations seek faster, more reliable ways to manage increasingly complex data environments. Intone Data Integrator (IDI) is designed to simplify data management and integration through a no-code and low-code approach.
The platform provides more than 1000+ data connectors, end-to-end encryption, centralized password management, real-time and batch processing, lineage tracking, in-memory operations, and an intuitive monitoring module. These capabilities help businesses connect diverse systems, automate data movement, improve visibility, and reduce the complexity associated with traditional integration projects.
Maximizing Efficiency with Data Integration Effective data integration is no longer simply a technical requirement; it is an important foundation for modern business intelligence and informed business decision-making. By connecting fragmented information, improving data quality, resolving conflicts, and supporting scalable analytics, organizations can transform raw data into practical insights.
The right integration strategy also enables businesses to adapt as data sources and operational requirements evolve. With a solution such as Intone Data Integrator, organizations can simplify integration of workflows, improve data accessibility, and build a stronger foundation for analytics, governance, and long-term digital transformation.
FAQ’s
Data integration in data mining is the process of consolidating and harmonizing data from multiple heterogeneous sources into a single unified dataset for improved analysis and pattern detection.
Tight coupling extracts, transforms, and physically loads data into a centralized data warehouse (ETL). lose coupling queries source databases directly via an interface without moving the physical underlying data.
Continuous controls monitoring constantly evaluates controls and exceptions across integrated systems, relying on clean, traceable data pipelines to maintain audit readiness and operational governance.
Data quality management eliminates duplicate tuples, resolves schema conflicts, and ensures formatting consistency, preventing bad or mismatched data from distorting analytical outcomes.
Intone Data Integrator provides over 1000+pre-built connectors, low-code/no-code pipeline design, end-to-end encryption, and in-memory processing to accelerate enterprise integration projects.
Data integration improves data mining by combining data from multiple sources, improving data quality and consistency, and enabling more accurate analysis and decision-making.